Everpure expands data management capabilities for production AI at scale

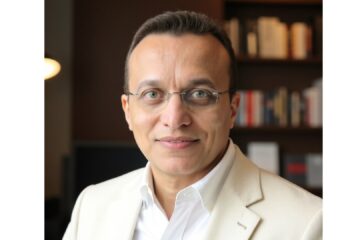
Prakash Darji, General Manager, Data & Digital Experience at Everpure.
Everpure has announced new platform capabilities designed to simplify enterprise data management, advancing its Data Primacy vision. Introduced at Pure//Accelerate in June, Data Primacy is the principle that data—not applications—must be the core driver of enterprise architecture in the AI era. Today’s updates continue to advance the modern data management capabilities required to solve bottlenecks stalling enterprise AI at scale: fragmented context, unpredictable inference costs, and slow, complex deployments.
“Enterprise AI is hitting a wall not because the models are lacking, but because data is not ready for real-time, autonomous agents. We are eliminating that friction. By making enterprise data continuously governed, automated, and instantly accessible, we’re giving organizations the foundation to move AI out of the lab and into production with the necessary confidence,” said Prakash Darji, General Manager, Data & Digital Experience at Everpure.
Enterprises deploying AI agents often struggle to give them reliable, governed access to data across the business, limiting how much those agents can actually achieve. Everpure Data Intelligence solves this by discovering, classifying, and contextualizing enterprise information at its source—spanning the Everpure Platform, public clouds, SaaS applications, and third-party storage. Building on this, new capabilities give autonomous agents and administrators direct, secure access to live enterprise context without custom API work.
Native integration with the open Model Context Protocol (MCP) enables AI agents and security tools to query live data catalogs using natural language. Agents can identify relevant data and understand its sensitivity classification to support AI applications, agent workflows and analytics.
Deployment is simplified through the existing Pure1 console, eliminating the need for complex professional services engagements or separate management servers. This accelerates time-to-value while reducing operational overhead.
Privacy-first file intelligence provides visibility into who can access each file share and how long it has remained inactive, without reading file content. This enables teams to address potential exposure risks and reclaim storage capacity before making file shares accessible to AI agents.
To support growing workloads from archive to AI, Everpure is expanding performance and capacity efficiency without disrupting operations. The new capabilities bring high-performance AI execution directly to data at the source, delivering production-level speed without moving data from its system of record.
Everpure FlashBlade now pre-stages context directly into GPU memory, delivering up to 20 times faster Time to First Token (TTFT). It supports enterprise multi-tenancy without requiring dataset relocation, reducing GPU idle time, increasing token throughput and minimising response lag for real-time applications.
The new Always-On DeepReduce Data Compression capability continuously scans storage blocks across FlashBlade systems to identify sub-block data similarities that traditional deduplication methods may miss, even in pre-compressed content. This automatically expands usable storage capacity without affecting write performance or requiring manual scheduling, while significantly reducing hardware footprint and cross-cloud expenses.
Everpure has also introduced an Intelligent Token Optimization Reference Architecture using open-weight models, enabling enterprises to retain greater control over their data while optimising AI expenditure. The architecture helps organisations achieve more predictable AI costs by reducing their reliance on API tokens from external providers.
Individually, these capabilities close specific gaps in simplicity, security, performance, and cost. Together, they give enterprises a single, continuously updated foundation for managing their data and running AI in production, built to keep pace as agentic workflows scale. Because these capabilities classify what data is sensitive and who touches it, they also strengthen cyber resilience, since the same context that makes data safe for AI to use is what determines how it gets protected and what gets recovered first.

Leave a reply